The problem
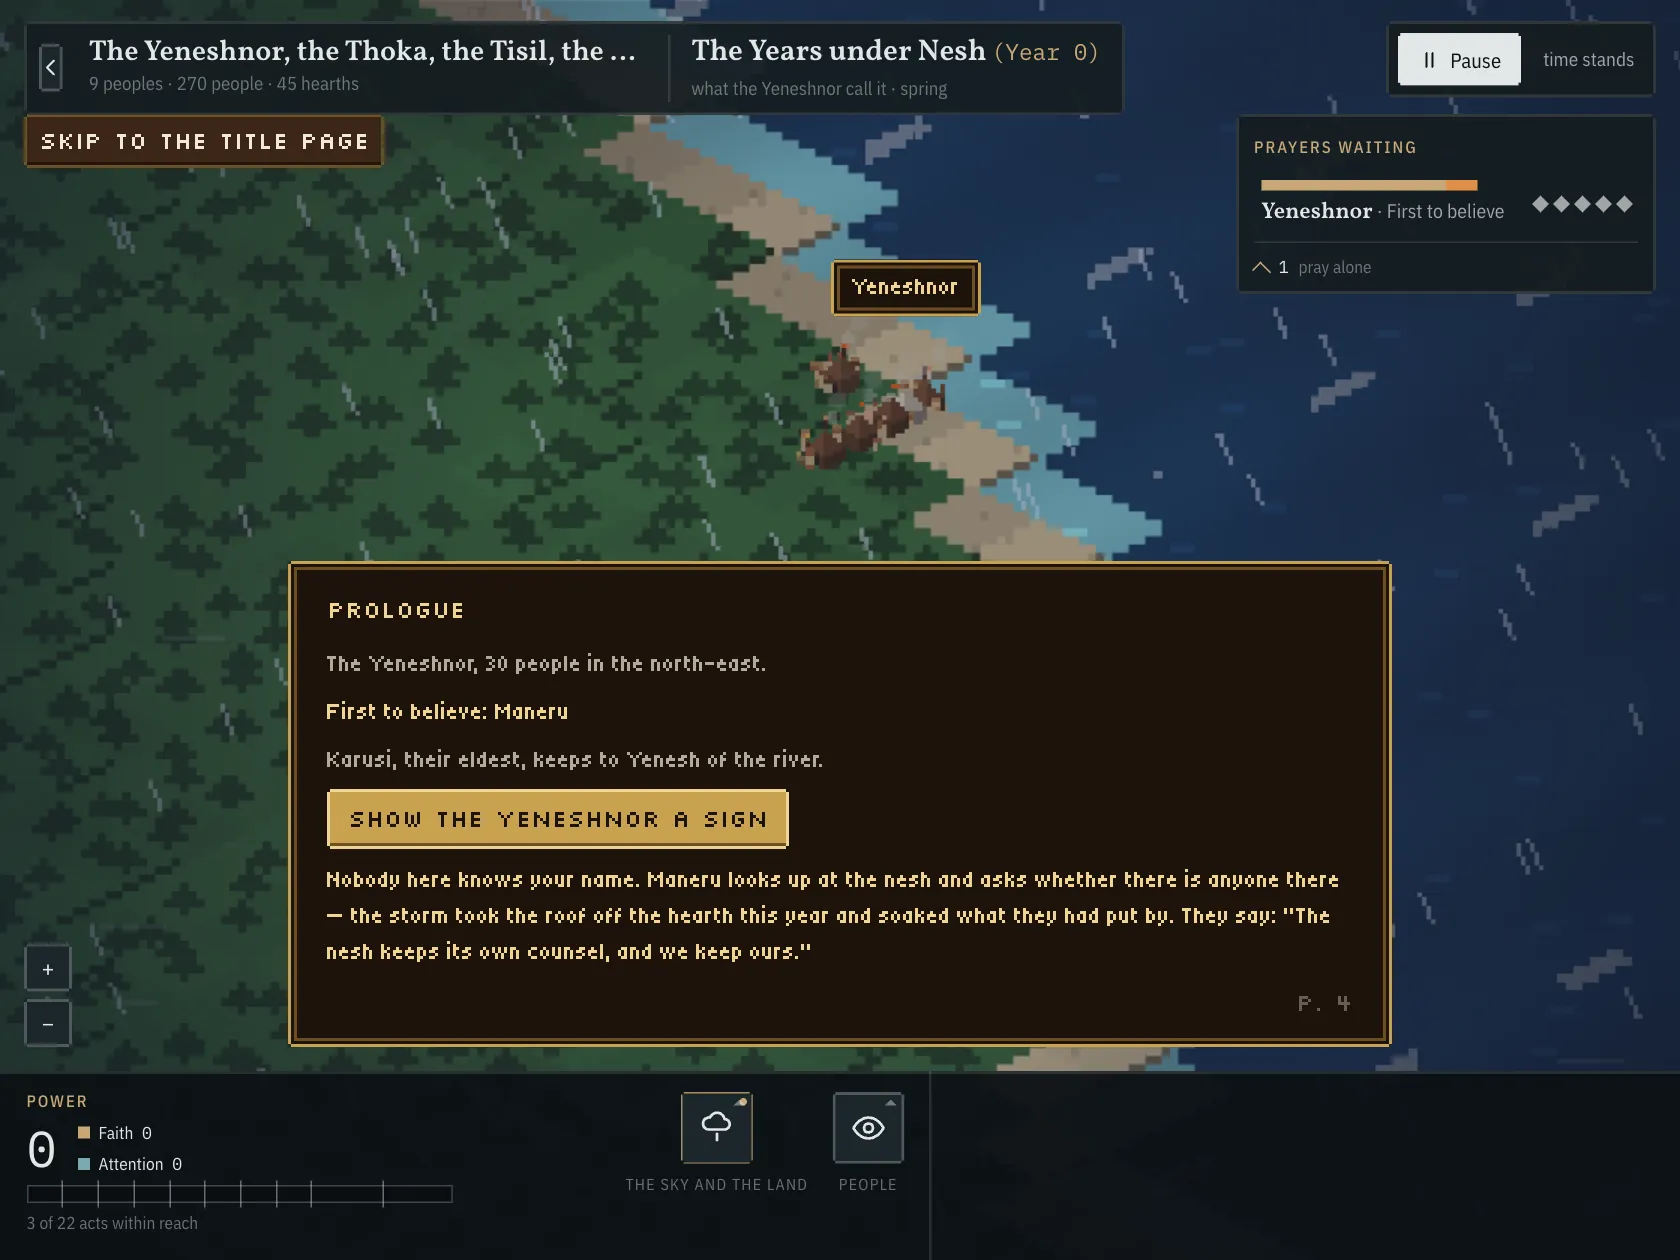
I wanted a god game with nothing scripted. People pray to you in their own words, you answer through the world, and they invent things on their own until they come to worship you or work out that their world was made. That means a seeded simulation that replays exactly, and models that can only propose: the rules decide what happens.
Who did what
CLAUDE.md says it directly: I set the direction and write the specs, and Claude Code implements. My calls are tagged [Direction] in the decision log. Architecture changes wait for my OK. Claude Code is co-author on 482 of 483 commits.
Constraints
- The simulation is deterministic: one seeded random generator, and a lint rule that bans
Math.randomandcryptoinside it. A saved world is its seed plus a log of commands. - The AI proposes and the rules decide. A model never changes the world directly.
- The game runs on local models only, and everything has to run on a 16 GB M3 Mac.
- Claude Haiku is the one cloud model, used to make training data and as the benchmark in blind comparisons, capped at $20 a month.
The trade-off
In September I took cloud models out of the game. Free Gemini calls for big moments and players’ own API keys both went, so the game runs only on what is on the machine. Each AI job gets a small trained model once one qualifies, and qwen3:8b covers the rest. If an answer is still invalid after one retry, or the call times out, the rules answer instead.
Outcome
- Still a prototype: the first playable version is next on the plan. 483 commits from September to October 2026.
- About 680 test cases in 62 files. One replays 60 years of a world and checks that all 240 season hashes come out identical.
- In the first model benchmark,
qwen3:8breturned valid output 100 times out of 100, at a median of 24.4 seconds per call.
How it was built
CLAUDE.mdholds 12 hard rules, from “the sim is pure” to “ask before adding any dependency”.- Six skills hold the procedures.
sim-ruleslists what breaks determinism,ai-calldefines the parts every model call needs,measuresweeps about ten seeds before a number is reported, andlog-decisionkeeps the decision log append-only. - Two Sonnet agents:
spec-finderquotes only the spec passages that answer a question, andworld-runnerruns headless benchmarks and reports the numbers without touching code or tests.